SovranCode
Modern C++ Lesson 45
Course contents50 available · 0 planned

Get a program running

01 · C++ Introduction: What Is C++?02 · How to Install a C++ Compiler and Set Up Your Editor03 · C++ Hello World: Your First Program Explained04 · How to Compile and Run C++ Programs05 · C++ Debugging: Warnings and Breakpoints

Work with values and input

06 · C++ Variables: Initialization and Scope07 · C++ Data Types: int, double and Type Conversion08 · C++ const, constexpr and auto Explained09 · C++ Operators: Arithmetic, Comparison and Logic10 · C++ User Input: cin, getline and Validation

Control flow and functions

11 · C++ Conditions: if, else if and else12 · C++ Switch Statement: Cases, break and default13 · C++ For Loop: Syntax and Examples14 · C++ While and Do-While Loops: Examples15 · C++ Functions: Parameters and Return Values

Strings and sequences

16 · C++ Strings: std::string with Examples17 · C++ Vector: std::vector with Examples18 · C++ Arrays: std::array and Bounds Checking19 · C++ Range-Based For Loop and Iterators20 · C++ Vector Practice: Build a Data Summary

Model data with classes

21 · C++ Structs and enum class Explained22 · C++ Classes and Objects: Encapsulation23 · C++ Constructors and Member Initialization24 · C++ Const Member Functions and Composition25 · C++ Copying Objects and the Rule of Zero

Lifetime and resource ownership

26 · C++ Object Lifetime, Destructors and RAII27 · C++ Pointers and References: nullptr and Borrowing28 · C++ unique_ptr: Smart Pointers and Ownership29 · C++ Move Semantics: std::move vs Copying30 · C++ string_view and span: Avoid Dangling Views

Containers and algorithms

31 · C++ map vs unordered_map: Lookup and Examples32 · C++ set, queue and stack: When to Use Each33 · C++ Lambda Expressions and STL Algorithms34 · C++ sort and binary_search: Rules and Complexity35 · C++20 Ranges: Views, filter and transform

Errors, files, and interfaces

36 · C++ optional and variant Explained37 · C++ Exceptions: try, catch and Safe Cleanup38 · C++ File Handling: Read and Write Text Files39 · C++ Input Parsing and Data Validation40 · C++ Polymorphism: Virtual Functions and Interfaces

Generic programming and quality

41 · C++ Templates: Function and Class Examples42 · C++20 Concepts and Template Constraints43 · C++ Unit Testing: Normal and Boundary Cases44 · C++ Sanitizers: Find Memory and Undefined Behavior Bugs45 · C++ Performance: Benchmark Before Optimizing

Build and deliver a complete application

46 · C++ Header Files and Translation Units47 · C++ CMake Tutorial: Build an Executable48 · C++ Dependencies and CTest: Automated Tests49 · C++ Multithreading: Threads and Data Races50 · C++ Command-Line Applications: Help and Release Checks
Modern C++50 available · 0 planned

Get a program running

01 · C++ Introduction: What Is C++?02 · How to Install a C++ Compiler and Set Up Your Editor03 · C++ Hello World: Your First Program Explained04 · How to Compile and Run C++ Programs05 · C++ Debugging: Warnings and Breakpoints

Work with values and input

06 · C++ Variables: Initialization and Scope07 · C++ Data Types: int, double and Type Conversion08 · C++ const, constexpr and auto Explained09 · C++ Operators: Arithmetic, Comparison and Logic10 · C++ User Input: cin, getline and Validation

Control flow and functions

11 · C++ Conditions: if, else if and else12 · C++ Switch Statement: Cases, break and default13 · C++ For Loop: Syntax and Examples14 · C++ While and Do-While Loops: Examples15 · C++ Functions: Parameters and Return Values

Strings and sequences

16 · C++ Strings: std::string with Examples17 · C++ Vector: std::vector with Examples18 · C++ Arrays: std::array and Bounds Checking19 · C++ Range-Based For Loop and Iterators20 · C++ Vector Practice: Build a Data Summary

Model data with classes

21 · C++ Structs and enum class Explained22 · C++ Classes and Objects: Encapsulation23 · C++ Constructors and Member Initialization24 · C++ Const Member Functions and Composition25 · C++ Copying Objects and the Rule of Zero

Lifetime and resource ownership

26 · C++ Object Lifetime, Destructors and RAII27 · C++ Pointers and References: nullptr and Borrowing28 · C++ unique_ptr: Smart Pointers and Ownership29 · C++ Move Semantics: std::move vs Copying30 · C++ string_view and span: Avoid Dangling Views

Containers and algorithms

31 · C++ map vs unordered_map: Lookup and Examples32 · C++ set, queue and stack: When to Use Each33 · C++ Lambda Expressions and STL Algorithms34 · C++ sort and binary_search: Rules and Complexity35 · C++20 Ranges: Views, filter and transform

Errors, files, and interfaces

36 · C++ optional and variant Explained37 · C++ Exceptions: try, catch and Safe Cleanup38 · C++ File Handling: Read and Write Text Files39 · C++ Input Parsing and Data Validation40 · C++ Polymorphism: Virtual Functions and Interfaces

Generic programming and quality

41 · C++ Templates: Function and Class Examples42 · C++20 Concepts and Template Constraints43 · C++ Unit Testing: Normal and Boundary Cases44 · C++ Sanitizers: Find Memory and Undefined Behavior Bugs45 · C++ Performance: Benchmark Before Optimizing

Build and deliver a complete application

46 · C++ Header Files and Translation Units47 · C++ CMake Tutorial: Build an Executable48 · C++ Dependencies and CTest: Automated Tests49 · C++ Multithreading: Threads and Data Races50 · C++ Command-Line Applications: Help and Release Checks
PREVIOUS LESSONC++ Sanitizers: Find Memory and Undefined Behavior Bugs
NEXT LESSONC++ Header Files and Translation Units
C++ foundations · Lesson 45 About 51 min with practice

C++ Performance: Benchmark Before Optimizing

Learn C++ performance measurement without fake speed claims: verify lookup correctness, separate sorting setup, time real work with steady_clock, and report workload and compiler limits.

Before you begin

Know vectors, find, binary_search, sorting, tests and lambdas. Timing output varies by machine and run; no winner or fixed duration is promised.

What you will learn

  • Check correctness before comparing execution time.
  • Separate preparation cost from repeated lookup cost.
  • Use steady_clock for elapsed-time intervals.
  • Keep benchmark results observable and report the workload.
  • Describe noise, optimization and limits without claiming universal speedups.

Faster is useful only when the answer is still right

Imagine two ways to find a reading: inspect the unsorted vector with find, or search a sorted copy with binary_search. Before timing them, check that both answer the same question for the same requests. A fast wrong answer is not an improvement. Correctness checks belong before the measurement so a bug does not become a convincing-looking performance result that the student later repeats without understanding.

A benchmark is a controlled attempt to measure work under stated conditions. It is not one number that applies to every machine or every input. Record the compiler, optimization flags, data size, query mix and what the timed interval includes. Keep the original workload meaningful. A tiny classroom example can explain measurement mechanics, but it is not evidence that a particular data structure will be best for your production application.

Sorting has a preparation cost. If the data is already kept in sorted order, repeated binary lookup may be useful. If there is only one query on unsorted data, a linear scan can be simpler and avoid the setup. State whether you include sorting in the comparison. Hiding a required preparation step can make a timing result answer a different question from the one your user actually cares about.
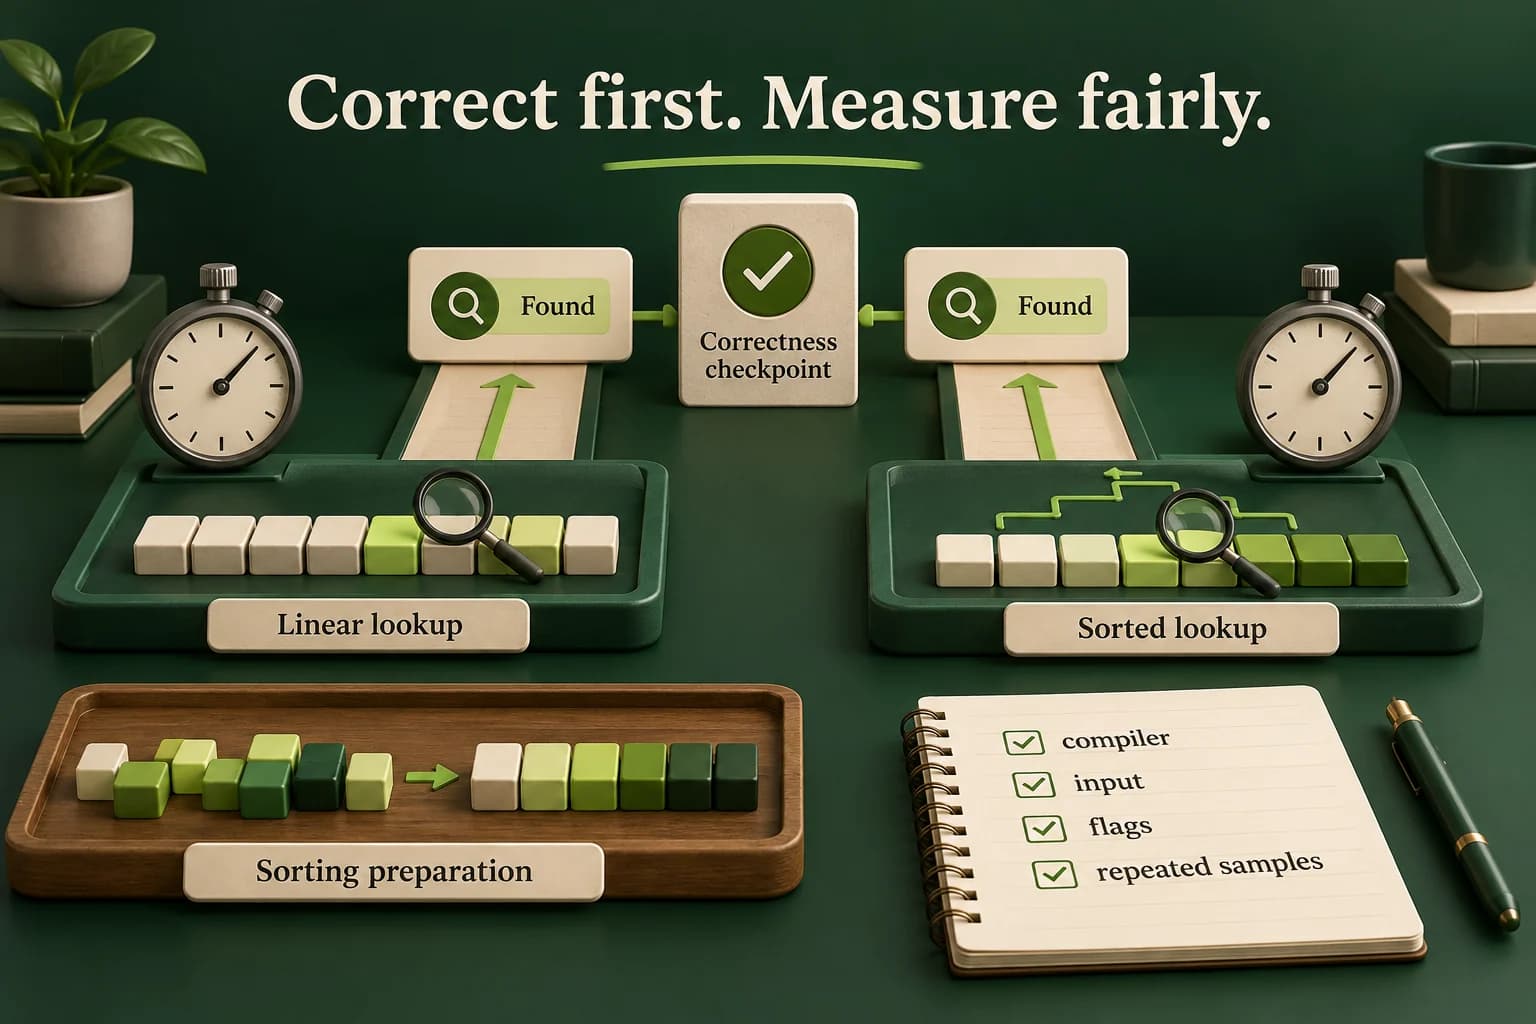
Two lookup strategies first pass a correctness comparison. Their later timing lanes are separate from sorting preparation, and a notebook records compiler, flags, inputs and repeated samples. No stopwatch displays an invented winner or speedup.
Compare equal behavior before timing, state where setup is counted, and record real samples. The teaching workload is synthetic; neither an illustration nor one run establishes a universally faster strategy.
C++ PRACTICE RUNNER

First check that two strategies agree

Sort a copy so the original input order remains available. The result is about correctness, not speed.

#include <algorithm>
#include <iostream>
#include <vector>
int main() {
    const std::vector<int> values{7, 2, 5, 2};
    auto sorted = values;
    std::sort(sorted.begin(), sorted.end());
    const int query{5};
    const bool linear = std::find(values.begin(), values.end(), query) != values.end();
    const bool binary = std::binary_search(sorted.begin(), sorted.end(), query);
    std::cout << std::boolalpha << "Found: " << linear << "\nAgreement: " << (linear == binary) << '\n';
}
TERMINAL OUTPUT
Predict the output, edit the source, then select Run code.

C++20 compiler runner: source and input are sent only when you press Run to this website's execution endpoint, not an external vendor. Local preview requires Docker and gcc:14; production requires a separately isolated execution service. Network is disabled; execution is limited to 3 seconds, compilation to 10 seconds, memory to 384 MB and output to 32 KB. Single-file programs only. Don't enter secrets. Edits reset on refresh; Copy your work to keep it.

Compare with the starter's expected output
Found: true
Agreement: true

After editing inputs, calculate a new prediction; this reference describes only the starter.

Be clear about the question you are measuring

The first program copies the vector, sorts the copy and checks one requested value with both strategies. Duplicates stay present, but either strategy still answers whether at least one match exists. Test present and missing queries before timing, including empty data. Do not call binary_search on the unsorted original merely because that avoids preparation. A faster-looking program outside the algorithm's required conditions is not a valid comparison.

The measurement example generates bounded synthetic data and queries. It is useful for practising the process, not a claim of real customer traffic. It records sorting time separately, validates agreement for every generated query, then times repeated linear and binary lookups. The repeated hit totals are printed afterward so the calculated results are observable. Standard output is outside the timed lookup loops to avoid measuring terminal printing as part of each search.

A clock interval uses a start time, the work, and a finish time. steady_clock is intended for elapsed-time measurement without wall-clock adjustments moving the clock backward. Converting its duration to nanoseconds chooses a reporting unit; it does not guarantee one-nanosecond hardware accuracy. Very short tasks can produce coarse or zero-looking samples. Increase useful repeated work carefully rather than pretending that more decimal places create better evidence.

  • Create data and a separately sorted copy.
  • Verify both strategies agree on every generated query.
  • Time bounded repeated work while keeping results observable.
  • Print real durations and workload details, not a fixed expected speedup.
C++ PRACTICE RUNNER

Measure a bounded lookup workload

Variable output: enter item count 0..1000 and query count 1..2000 on separate integer lines. Durations are real observations, not fixed expected output. The workload repeats twenty times; compiler optimization can still affect this small teaching harness.

#include <iostream>
#include <sstream>
#include <string>
bool readInteger(int& value) {
    std::string line;
    if (!std::getline(std::cin, line)) return false;
    std::istringstream parser{line};
    if (!(parser >> value)) return false;
    parser >> std::ws;
    return parser.eof();
}
#include <algorithm>
#include <chrono>
#include <vector>
int main() {
    int count{}, queries{};
    if (!readInteger(count) || !readInteger(queries) || count < 0 || count > 1000
        || queries < 1 || queries > 2000) {
        std::cout << "Invalid input\n"; return 1;
    }
    std::vector<int> values;
    for (int i = count - 1; i >= 0; --i) values.push_back(i * 2);
    auto sorted = values;
    using Clock = std::chrono::steady_clock;
    const auto setupStart = Clock::now();
    std::sort(sorted.begin(), sorted.end());
    const auto setupEnd = Clock::now();
    std::vector<int> requests;
    for (int i = 0; i < queries; ++i) requests.push_back(i % (count * 2 + 1));
    for (int query : requests) {
        const bool a = std::find(values.begin(), values.end(), query) != values.end();
        const bool b = std::binary_search(sorted.begin(), sorted.end(), query);
        if (a != b) { std::cout << "Mismatch\n"; return 2; }
    }
    int linearHits{}, binaryHits{};
    const auto linearStart = Clock::now();
    for (int repeat = 0; repeat < 20; ++repeat)
        for (int query : requests)
            linearHits += std::find(values.begin(), values.end(), query) != values.end();
    const auto linearEnd = Clock::now();
    const auto binaryStart = Clock::now();
    for (int repeat = 0; repeat < 20; ++repeat)
        for (int query : requests)
            binaryHits += std::binary_search(sorted.begin(), sorted.end(), query);
    const auto binaryEnd = Clock::now();
    if (linearHits != binaryHits) { std::cout << "Mismatch\n"; return 2; }
    std::cout << "Queries: " << queries * 20 << "\nHits: " << linearHits
        << "\nSort ns: " << std::chrono::duration_cast<std::chrono::nanoseconds>(setupEnd - setupStart).count()
        << "\nLinear ns: " << std::chrono::duration_cast<std::chrono::nanoseconds>(linearEnd - linearStart).count()
        << "\nBinary ns: " << std::chrono::duration_cast<std::chrono::nanoseconds>(binaryEnd - binaryStart).count() << '\n';
}
TERMINAL OUTPUT
Predict the output, edit the source, then select Run code.

C++20 compiler runner: source and input are sent only when you press Run to this website's execution endpoint, not an external vendor. Local preview requires Docker and gcc:14; production requires a separately isolated execution service. Network is disabled; execution is limited to 3 seconds, compilation to 10 seconds, memory to 384 MB and output to 32 KB. Single-file programs only. Don't enter secrets. Edits reset on refresh; Copy your work to keep it.

A small harness has limits worth saying aloud

The setup interval here measures sorting only, not input parsing, data generation or the vector copy. That is intentional and must be stated when interpreting the report. The lookup intervals include loop overhead and the hit accumulation as well as the search work. They do not include terminal output. If your actual application has a different balance of setup, updates and queries, design a workload that measures that balance instead.

The benchmark always runs linear lookup before binary lookup. Earlier work and correctness checks can warm caches, and the compiler may optimize repeated calculations. Printing totals helps keep results observable but is not a universal optimizer barrier. More rigorous performance work can use a dedicated framework, vary order and workloads, and inspect generated code where justified. This teaching example is transparent about those limits rather than claiming laboratory precision.

Run several samples under the same build and input, then change one factor at a time. Keep raw observations, not just the most flattering run. Other processes, power settings, scheduling and memory state can change timings. Do not compare a sanitizer build of one strategy with an optimized normal build of another and call the difference an algorithmic result. Record enough environment information that another student understands what was actually compared.

LOCAL TERMINAL COMMANDS

Build a separate measurement executable

Use matching options for both strategies. These are example local optimization flags, not settings silently applied by the website runner. Record the actual compiler version and repeat the same accepted input for several runs.

clang++ --version
clang++ -std=c++20 -O2 -DNDEBUG -Wall -Wextra -Wpedantic main.cpp -o benchmark
./benchmark
# Provide the same item count and query count for each recorded sample.
# On a GCC environment, use g++ with equivalent supported options.
C++ PRACTICE RUNNER

Check the empty-data contract before timing it

Both algorithms correctly report absence for this valid empty range.

#include <algorithm>
#include <iostream>
#include <vector>
int main() {
    const std::vector<int> values;
    const bool linear = std::find(values.begin(), values.end(), 0) != values.end();
    const bool binary = std::binary_search(values.begin(), values.end(), 0);
    std::cout << std::boolalpha << linear << ' ' << binary << '\n';
}
TERMINAL OUTPUT
Predict the output, edit the source, then select Run code.

C++20 compiler runner: source and input are sent only when you press Run to this website's execution endpoint, not an external vendor. Local preview requires Docker and gcc:14; production requires a separately isolated execution service. Network is disabled; execution is limited to 3 seconds, compilation to 10 seconds, memory to 384 MB and output to 32 KB. Single-file programs only. Don't enter secrets. Edits reset on refresh; Copy your work to keep it.

Compare with the starter's expected output
false false

After editing inputs, calculate a new prediction; this reference describes only the starter.

Use growth rates as a guide, not a stopwatch

A linear search may inspect a number of elements proportional to the input size. A sorted vector lets binary search narrow its candidate area repeatedly, using logarithmic comparisons. Sorting first adds its own work. These growth descriptions help explain why workloads matter, but they do not directly predict the fastest option for a tiny vector or the exact time on a particular processor.

A result with many missing queries can differ from one where every query finds the first element. Repeated queries can differ from changing requests. Data that changes frequently may need repeated sorting or another structure entirely. Document the distribution and update pattern instead of reducing the decision to one comparison of two tiny hard-coded examples. Keep the simplest correct solution until evidence shows that its performance is a real problem.

When an observed difference is small or inconsistent, report that uncertainty. Do not invent an average you did not calculate, remove inconvenient samples without explanation, or promise a universal speedup. Good measurement notes can conclude that the experiment is too small or noisy to justify a change. That is a useful engineering result, not a failed lesson. Correctness and maintainability remain part of the decision even when one sample looks faster.

Verify lookup behavior, then record honest samples

The deterministic lab reads count zero through eight, that many integers from minus one hundred through one hundred, and one query in the same range. Validate all required lines before reporting. Search the original with find, sort a copy, search it with binary_search and require agreement. Print Found and Agreement with boolalpha. This source verifies equal behavior; it deliberately does not invent a timing result.

Then use the separate measurement example for at least three samples of one documented workload. Record compiler, optimization, item count, query count, which setup is included and the observed durations. Try a second workload and explain what changed. Keep the no-match, duplicate and empty correctness tests. The explained reference solution covers deterministic behavior, while your timing notes must come from actual measurements on your environment.

LOCAL TERMINAL COMMANDS

Build one complete safe example

Choose an installed compiler. These commands run locally, not in the source editor. The in-page Run button requires the configured compiler sandbox. Diagnostic fixtures and multi-file projects use their separate instructions.

macOS / Linux:
clang++ -std=c++20 -Wall -Wextra -Wpedantic main.cpp -o lesson
# Or use g++ with the same options.
./lesson

Windows Developer Command Prompt:
cl /std:c++20 /EHsc /W4 main.cpp /Fe:lesson.exe
lesson.exe
APPLY THE CONCEPT

Independent lab

Prove two lookup strategies agree, then investigate their cost with a documented real benchmark.

Acceptance checklist

  • Read count 0..8, bounded values -100..100 and a bounded query on complete lines.
  • Reject invalid required input as Invalid input with status 1 before output.
  • Use find on the original and binary_search on an ascending sorted copy; do not change arrival data.
  • Require agreement and print Found and Agreement using boolalpha, including empty and duplicate inputs.
  • Run the separate timing example for repeated samples and record actual workload, compiler, flags, setup scope and measurement limits.
Need a hint?
  1. Correctness comes before the stopwatch.
  2. The deterministic solution has no fabricated duration or guaranteed winner.
  3. A three-sample notebook describes observations; it is not automatically a statistically conclusive benchmark.
C++ PRACTICE RUNNER

Write and run your lab

Build your own solution before revealing the reference. Use the input field for normal, boundary and invalid cases; this runner executes your program but does not grade it.

#include <iostream>
#include <string>
#include <sstream>
#include <limits>

int main() {
    // Implement the acceptance checklist above.
    return 0;
}

TERMINAL OUTPUT
Predict the output, edit the source, then select Run code.

C++20 compiler runner: source and input are sent only when you press Run to this website's execution endpoint, not an external vendor. Local preview requires Docker and gcc:14; production requires a separately isolated execution service. Network is disabled; execution is limited to 3 seconds, compilation to 10 seconds, memory to 384 MB and output to 32 KB. Single-file programs only. Don't enter secrets. Edits reset on refresh; Copy your work to keep it.

Your lab evidence and notes

Record predictions, actual output, commands and the cause of each repair. Code is plain text: this scratchpad does not execute or grade C++.

Loading local notes…

Review your acceptance checklist and quiz explanations before marking this lesson complete. This is self-review, not a grade or certification.

Reveal the explained lab solution
C++ PRACTICE RUNNER

Reference lab solution

Compare the reference with your own reasoning. Running this solution does not grade or complete the lesson.

#include <iostream>
#include <sstream>
#include <string>
bool readInteger(int& value) {
    std::string line;
    if (!std::getline(std::cin, line)) return false;
    std::istringstream parser{line};
    if (!(parser >> value)) return false;
    parser >> std::ws;
    return parser.eof();
}
#include <algorithm>
#include <vector>
int main() {
    int count{};
    if (!readInteger(count) || count < 0 || count > 8) {
        std::cout << "Invalid input\n"; return 1;
    }
    std::vector<int> values;
    for (int i = 0; i < count; ++i) {
        int value{};
        if (!readInteger(value) || value < -100 || value > 100) {
            std::cout << "Invalid input\n"; return 1;
        }
        values.push_back(value);
    }
    int query{};
    if (!readInteger(query) || query < -100 || query > 100) {
        std::cout << "Invalid input\n"; return 1;
    }
    auto sorted = values;
    std::sort(sorted.begin(), sorted.end());
    const bool linear = std::find(values.begin(), values.end(), query) != values.end();
    const bool binary = std::binary_search(sorted.begin(), sorted.end(), query);
    if (linear != binary) { std::cout << "Mismatch\n"; return 2; }
    std::cout << std::boolalpha << "Found: " << linear << "\nAgreement: " << (linear == binary) << '\n';
}
TERMINAL OUTPUT
Predict the output, edit the source, then select Run code.

C++20 compiler runner: source and input are sent only when you press Run to this website's execution endpoint, not an external vendor. Local preview requires Docker and gcc:14; production requires a separately isolated execution service. Network is disabled; execution is limited to 3 seconds, compilation to 10 seconds, memory to 384 MB and output to 32 KB. Single-file programs only. Don't enter secrets. Edits reset on refresh; Copy your work to keep it.

Expected output

Found: true
Agreement: true

Both methods answer the same presence question, with the binary method operating on a correctly ordered copy.

The solution is a correctness check, not an unmeasured performance claim. The separate benchmark reports actual variable durations.

A decision needs representative workloads, setup costs and repeated observations. Neither the reference output nor a single fast sample establishes a universal winner.

Review before moving on

Explain the lesson's objectives in your own words, compare your lab evidence with the acceptance checklist, and keep the first failing case alongside your repair. Completing a page is not proof that every C++ feature or input is supported.

  • Check correctness before comparing execution time.
  • Separate preparation cost from repeated lookup cost.
  • Use steady_clock for elapsed-time intervals.
  • Keep benchmark results observable and report the workload.
  • Describe noise, optimization and limits without claiming universal speedups.

References and further reading

Original examples and exercises accompany these primary references. Tool-specific diagnostics and support depend on your installed version.

  • C++ draft: steady clock
  • Google Benchmark: user guide
  • C++ draft: binary search
KNOWLEDGE CHECK

Check your understanding

Answer all five questions, then review the explanations. Answers are not saved or synced; completion is a separate self-review choice.

01What must be checked before timing two implementations?
02Does a nanosecond reporting unit guarantee nanosecond accuracy?
03Should sorting cost be hidden when it is needed by the application?
04Does printing a checksum eliminate every optimizer effect?
05What if repeated samples show an inconsistent small difference?
PREVIOUS LESSONC++ Sanitizers: Find Memory and Undefined Behavior Bugs
NEXT LESSONC++ Header Files and Translation Units
ON THIS PAGELearning objectivesFaster is useful only when the answer is still rightBe clear about the question you are measuringA small harness has limits worth saying aloudUse growth rates as a guide, not a stopwatchVerify lookup behavior, then record honest samplesIndependent labReviewKnowledge checkReferences
Course overview